Claude Code Context Management: We Measured the 85% Reduction Claim. Here’s What We Found.
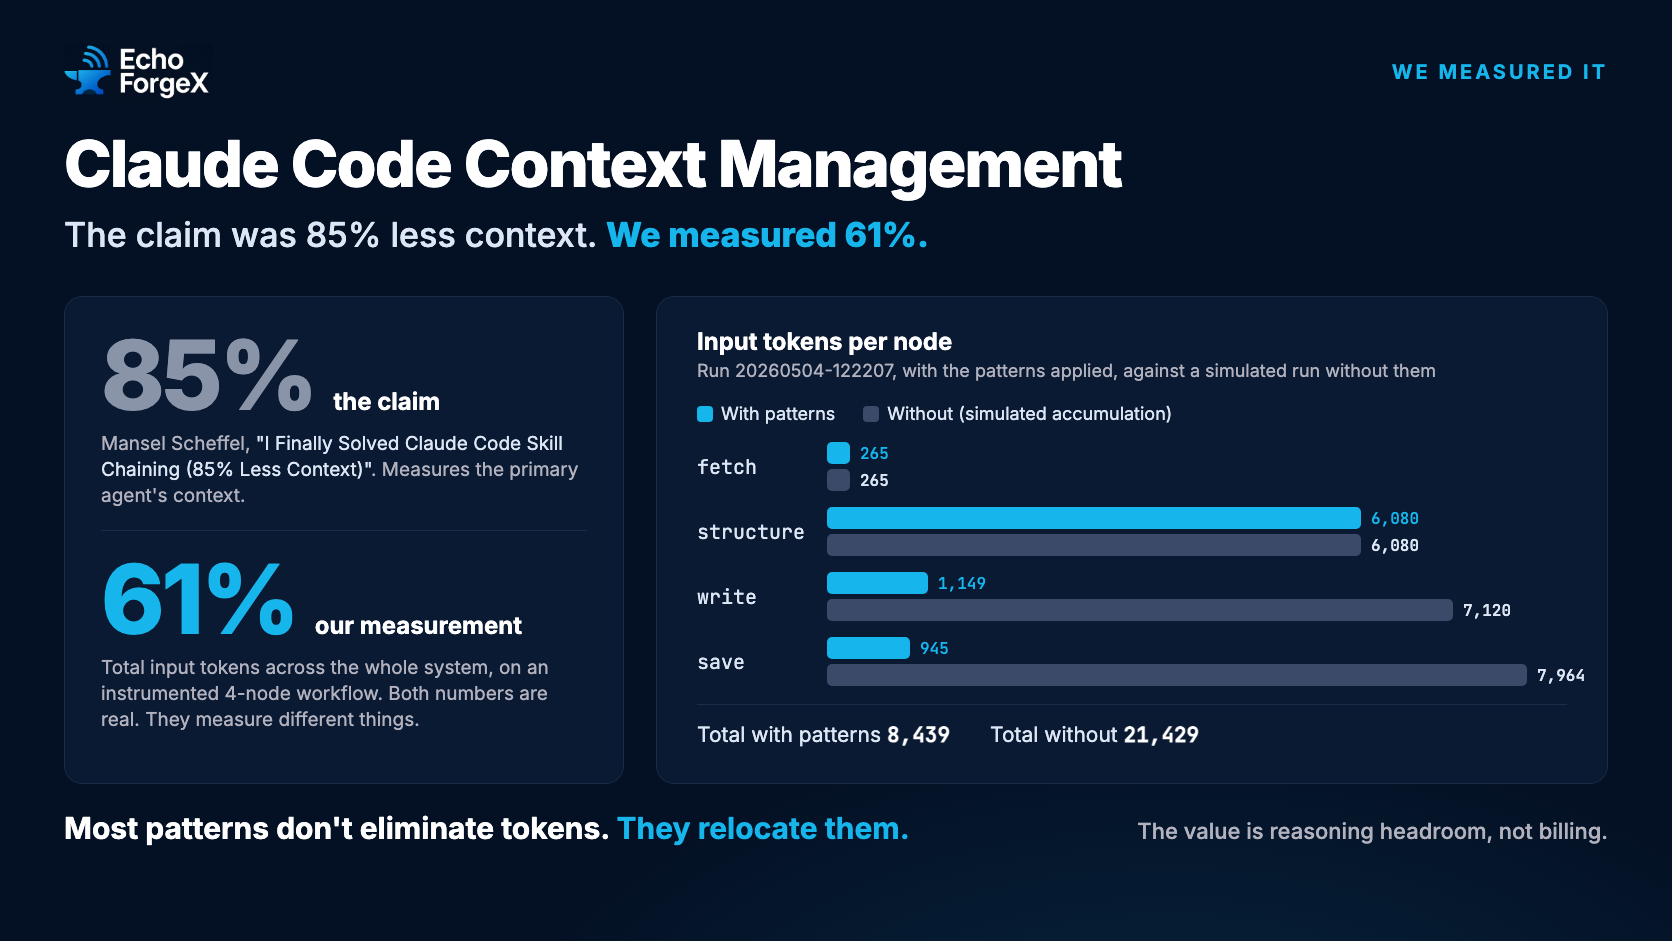
We instrumented Claude Code skill chaining to validate the 85% context reduction claim. Finding: 61%—and the value is reasoning quality, not billing.
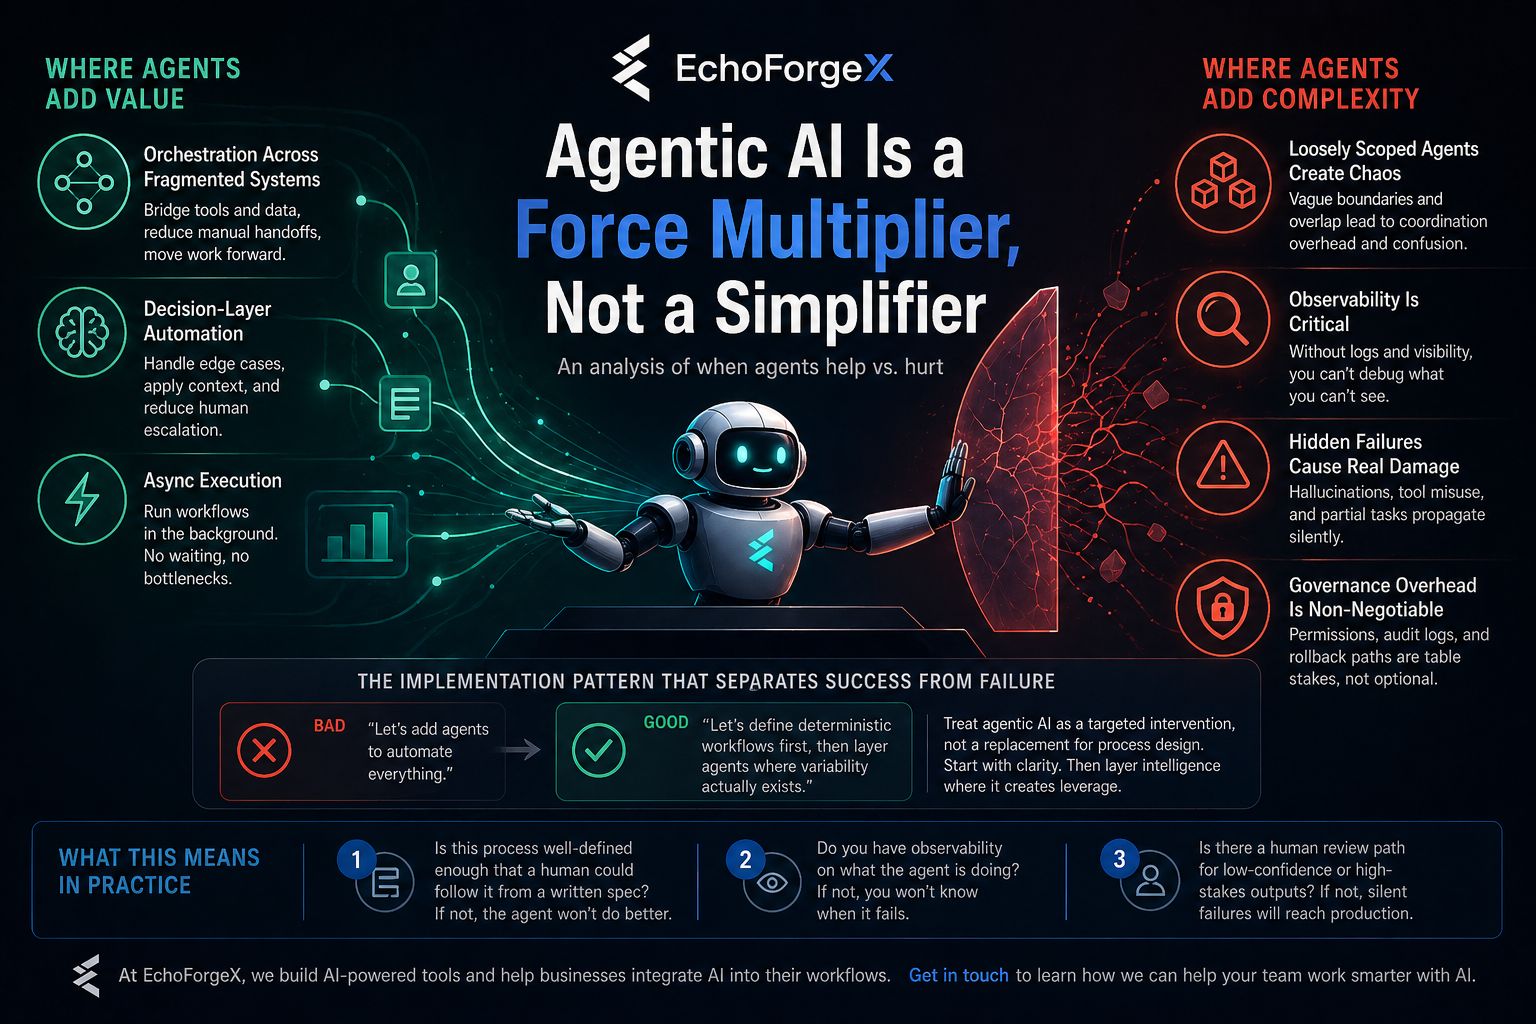
Agentic AI doesn’t simplify broken systems—it amplifies them. Learn when agents add real value and when they make chaos worse.
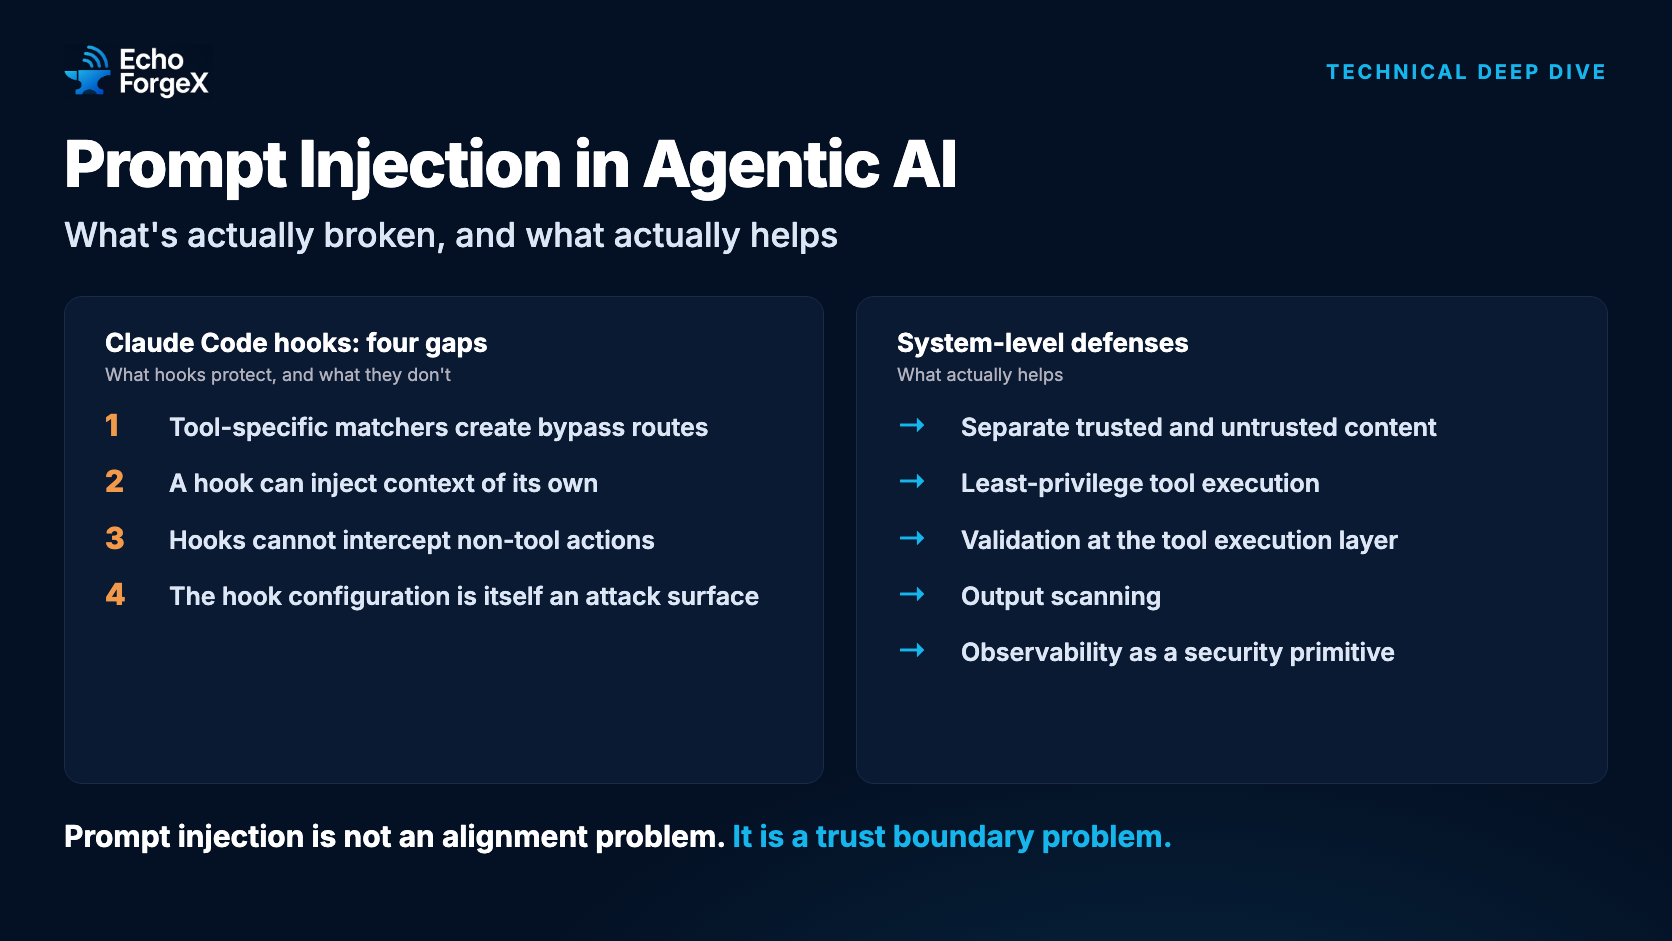
A detailed technical analysis of prompt injection vulnerabilities in agentic AI systems — Claude Code hooks, API tool execution, indirect injection, and why prompt engineering alone cannot fix this.
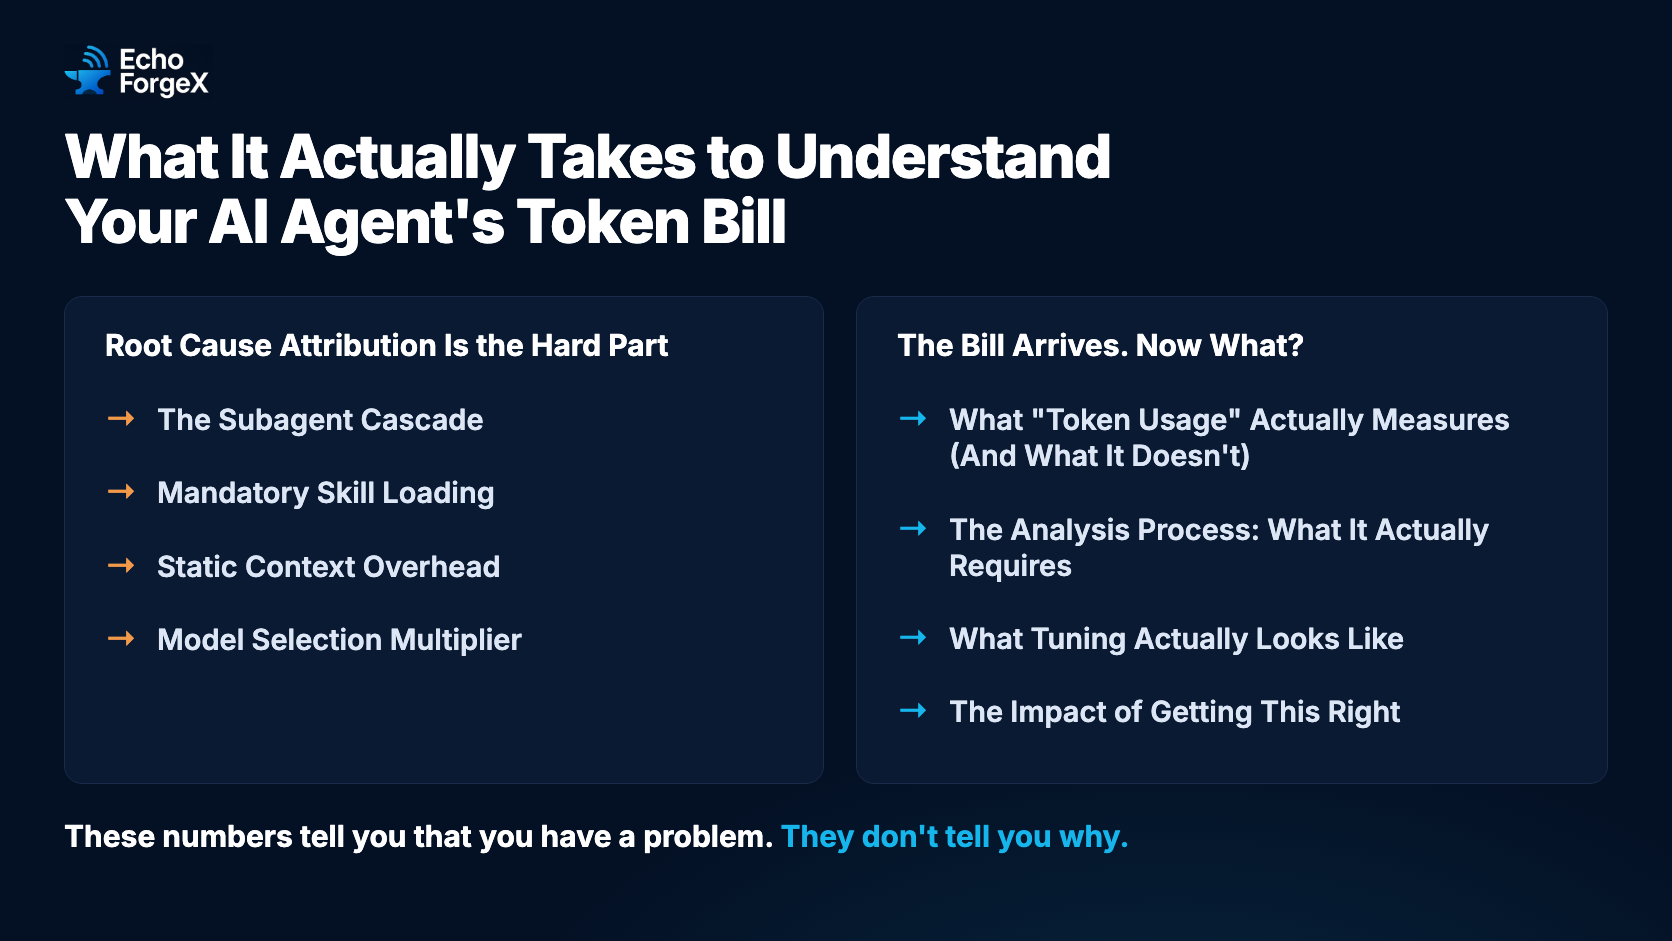
Debugging AI agent token costs is harder than it looks — especially with third-party plugins. Here’s what real analysis reveals.
Prompt injection is ranked LLM01 by OWASP. Learn how the attack works, why delimiters aren’t enough, and the layered defenses that actually hold up in production.
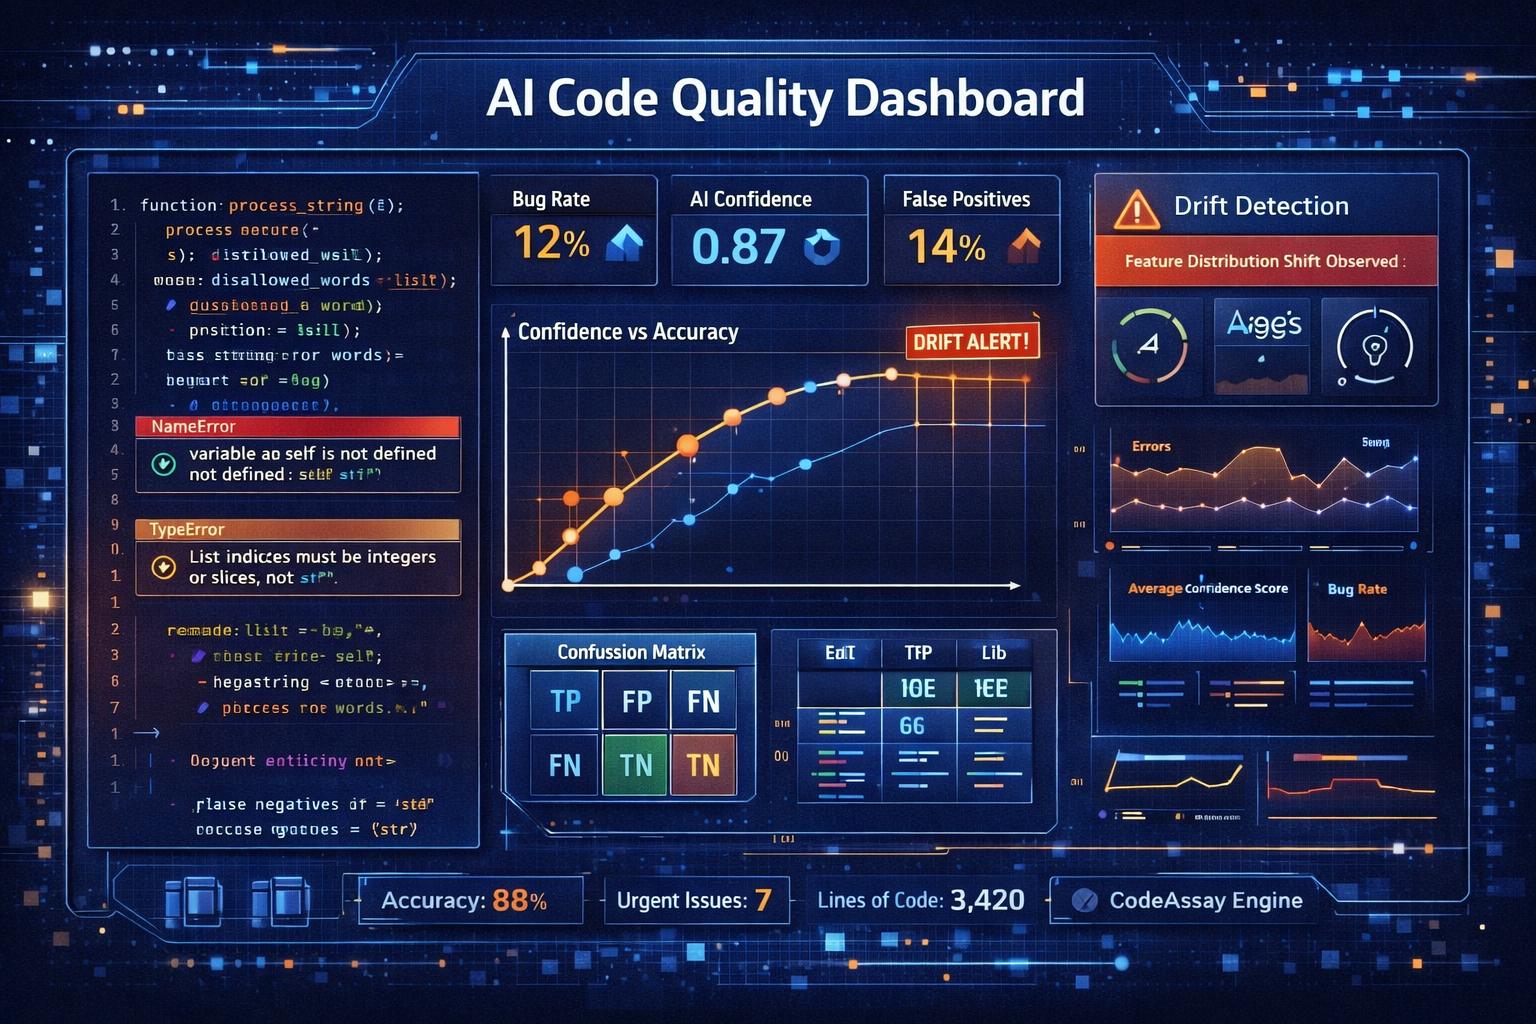
Track AI code quality with CodeAssay — detect rework, classify root causes, and visualize trends across your repos. Free, open source, zero dependencies.
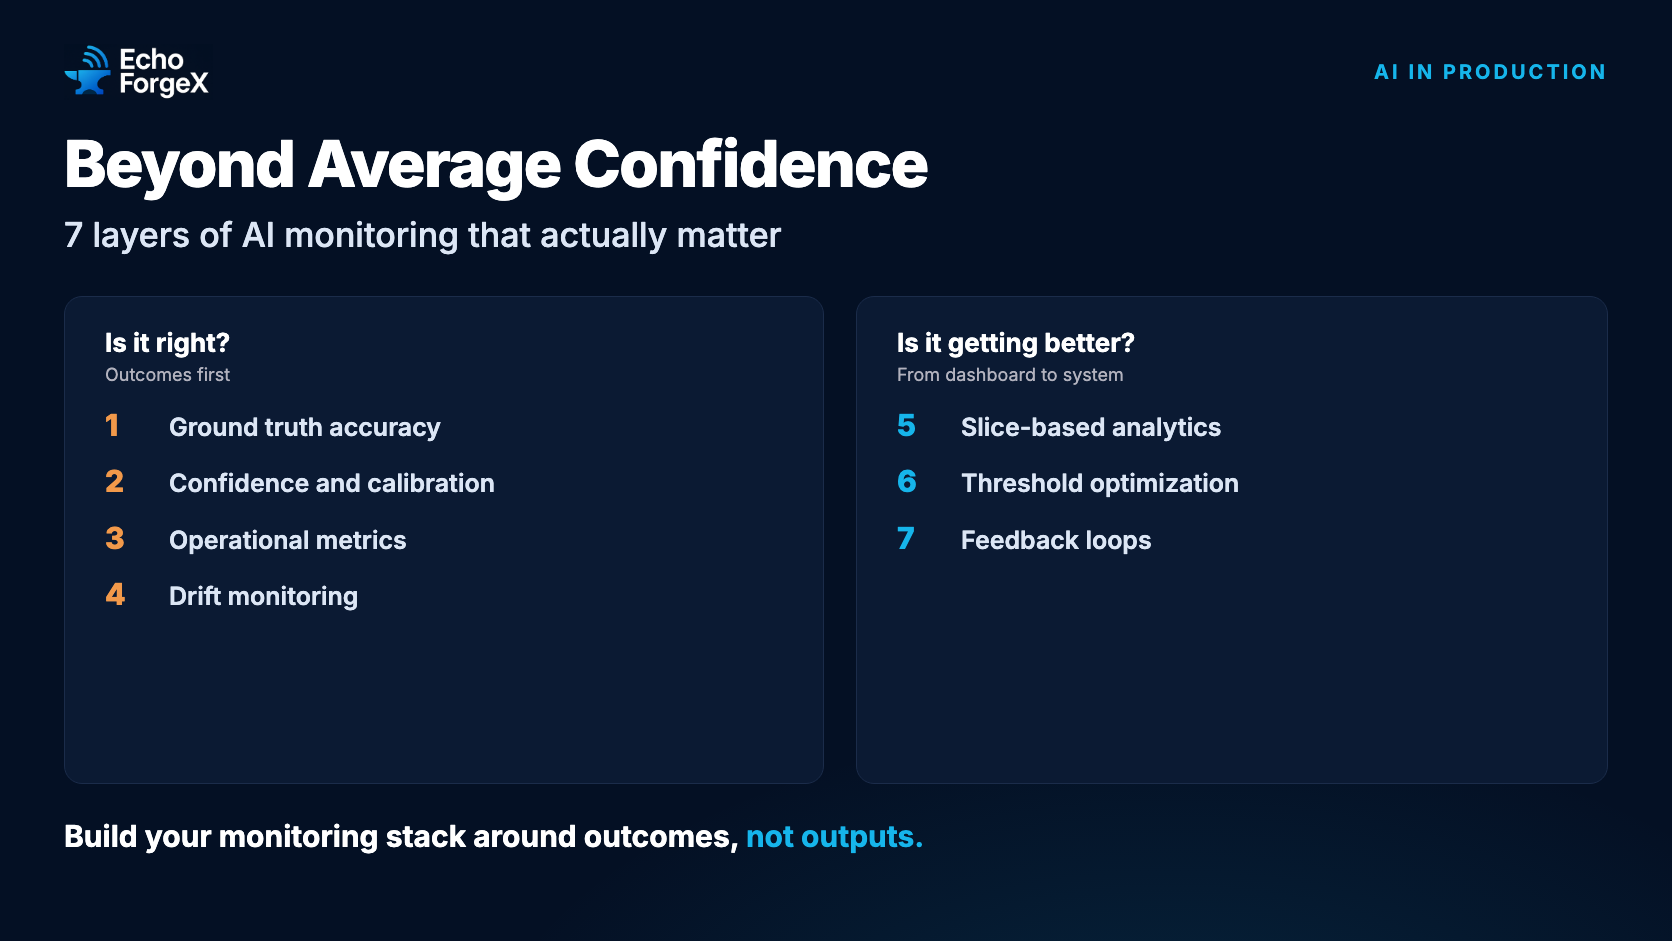
Average confidence scores mislead. Learn 7 layers of AI monitoring—from calibration curves to drift detection—that separate production systems from demos.
Vibe coding is fast and fun on toy projects. On large systems it silently accumulates debt. Here’s how to keep the flow without losing the rails.
Stop editing AI output. Start editing your prompts. Five pre-send checks that catch broken prompts before they cost you twenty minutes of cleanup.
Learn practical strategies to reduce AI token usage and costs across development, daily workflows, and production APIs without sacrificing quality.