
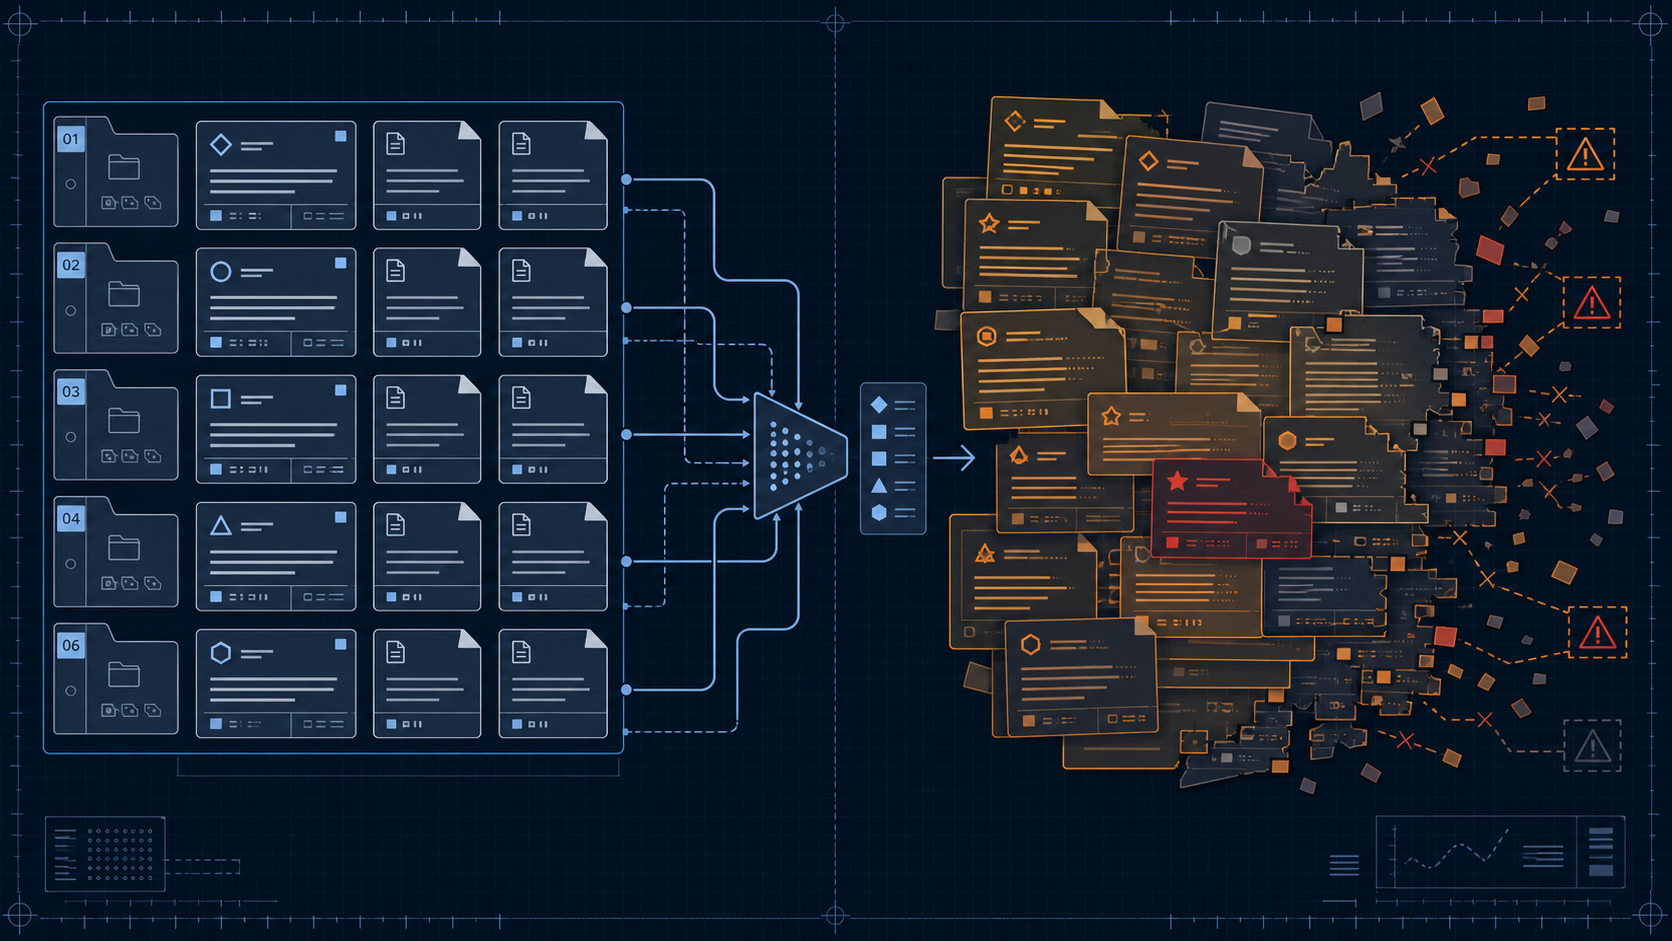
Building production AI systems at EchoForgeX has made one thing clear: models that score near 96% on instruction-following benchmarks (GPT-5 reaches 95.9% on IFEval, arxiv: 2512.14754) still break your rules in production. The failures aren’t random. They’re structural, and they compound as rule sets grow. Once you’ve shipped a few real agents — routing, classification, response generation, intake triage — you stop wondering whether the model followed the rules this time and start asking what it would take to make rule-following reliable by design.
This piece is about why prompting alone is insufficient for governing AI behavior, what the failure modes look like at the architectural level, and the direction we’re taking in our own tooling to address them.
The Attention Budget Problem
Every token in an LLM’s context window competes for the same attention budget. When governance rules are encoded in a system prompt — “always validate input before routing”, “never expose user PII”, “classify intent before responding” — those rules share context with the task description, conversation history, tool definitions, and any retrieved content. As context grows, rule adherence degrades. Not occasionally. Predictably.
The problem compounds quickly in real systems. Consider a support routing agent: system prompt with governance rules, tool definitions, a conversation history spanning several turns, and content retrieved from a knowledge base to inform the response. By the time the model begins reasoning about the current message, the governance rules at the top of the system prompt may be hundreds or thousands of tokens removed from the most recent input. Attention in transformer architectures doesn’t uniformly weight all prior context — recency and token position play a meaningful role in what the model effectively “sees” when generating a response. The rules you care most about are often the ones competing hardest against the user’s immediate request.
A December 2025 study benchmarking instruction-following reliability across 20 proprietary and 26 open-source LLMs found that model performance drops by up to 61.8% when prompts are modified in ways that introduce nuance — different phrasing, additional context, or adjacent constraints. Models that appeared reliable in controlled testing showed substantial failure under real-world conditions where users write questions differently than the evaluation set. The study’s conclusion is worth citing directly: near-ceiling scores on widely adopted benchmarks “do not necessarily translate to reliable services in real-world use, where users often vary their phrasing, contextual framing, and task formulations.” (arxiv: 2512.14754)
This is not a calibration gap. It’s a measurement gap. The benchmarks aren’t testing what breaks in production.
The Prompt Engineering Trap
The instinctive response to these failures is to improve the prompts. Write more specific rules. Add examples of correct behavior. Use structured reasoning — chain-of-thought, step-back prompting — to force the model to verify rule compliance before generating a final response. These techniques help at the margins. A more precise rule formulation does reduce ambiguity. Structured reasoning catches some violations before they reach the output.
But prompt engineering treats a capacity problem as a clarity problem. The underlying issue isn’t that rules are poorly written — it’s that every additional rule, example, and reasoning instruction added to a prompt consumes context that the model must attend to simultaneously. At some point, making the governance layer more thorough makes the problem worse, not better. You’re solving rule violation by adding more rules to the same pool of tokens that’s already failing to hold the existing ones.
The context window size argument doesn’t resolve this either. As models ship with larger context windows — 128k, 200k, 1 million tokens — the temptation is to treat capacity as a solution: just include all your rules all the time, at any scale. A bigger window raises the ceiling on what fits; it does not make the model attend to all of it equally. A rule that must be maintained across a range of output — exactly the kind of governance rule that matters most in production — has to survive more of that context than a single-step instruction does. Adding capacity doesn’t fix the attention distribution problem; it changes where the degradation curve starts.
The practical implication: if your AI governance strategy depends on the model reliably attending to an ever-growing set of prompt-encoded rules, you’re managing a reliability problem that can’t be engineered away at the prompting layer.
Conflicting Constraints Compound the Problem
Real applications don’t have one rule. They have dozens, and those rules interact. A routing agent in a customer support context might carry all of the following simultaneously: classify confidence must exceed a threshold before routing; never route to billing without first confirming account identity; format responses as structured JSON; escalate anything involving account deletion to a human queue; respond within a defined token budget. Each rule individually is straightforward. Together, they create constraint combinations the model must navigate in real time.
Research on conflict handling found that when two formatting constraints conflict, six models followed the one they were told to prioritize only 9.6% to 45.8% of the time on average, against 74.8% to 90.8% when each constraint was tested alone. (arxiv: 2502.15851) When a message simultaneously triggers the billing-confirmation rule, the escalation rule, and the token-budget constraint, the model will satisfy some of them. Which ones varies by input.
This is not a matter of writing better prompts. A model that handles each rule correctly in isolation will fail a predictable percentage of the time when those rules must be applied together under realistic conditions. The failure rate scales with rule complexity, not just rule count.
Intent Parsing Adds a Second Layer of Failure
Governance rules are only useful if they’re applied to correctly understood inputs. This is where AI applications encounter a structural problem that sits upstream of rule application: intent is ambiguous, and the model doing the interpreting is the same model being governed.
When you ask an LLM to parse user intent and then apply governance rules to that parsed intent, you create a two-step chain where errors from each step compound. A misclassified intent routes to the wrong handler before any governance rule is checked. A correctly classified intent with incomplete context causes a handler to apply rules against assumptions that weren’t grounded in the original message. Across multiple agents in a pipeline, these failures propagate — each agent receiving the output of the prior one, none of them with visibility into where the chain broke. A Hacker News discussion of agent workflow reliability framed this as classic distributed-systems failure modes appearing in multi-model setups: the system produces an output, the output is plausible, and no single agent observes the full failure.
The specific failure mode we’ve encountered most at EchoForgeX is what might be called intent drift under reformulation. A user who asks the same question three different ways — with different phrasing, in different positions in a conversation, after different prior exchanges — may receive governance treatment as if they sent three different intents. The rules being applied aren’t changing. The model’s read of what the user wants is. Governance built on top of a model that can’t consistently classify the same intent is governance with a variable input it doesn’t control.
The problem sharpens at context boundaries. Long conversations, large retrieved documents, and detailed instruction sets push toward the edges of what a model can attend to simultaneously. A rule that must be upheld across an entire response has to hold for every token the model generates, not just the first, so it has more chances to be dropped. If your governance rules are the end-to-end kind, that is the exposure to plan for as context grows.
The Architectural Answer: External Rule Libraries
The standard industry response to these failures has been adding guardrail layers — pre-LLM and post-LLM checks that run deterministically around the model rather than inside it. The pattern, formalized in the arxiv “Policy-as-Prompt” paper (2509.23994) and documented in practitioner resources from teams like Arthur AI and Patronus, separates what needs to be deterministic from what needs to be generative. Regex-based input checks, structured output schemas, and rule-based classifiers don’t compete with the model’s attention budget because they don’t live inside the prompt.
This is the right direction. Deterministic pre-checks run before the model sees the input. Post-output validators catch violations before they reach the user. Neither approach asks the model to self-govern, which means neither is subject to the attention and context degradation problems described above. For binary governance decisions — “does this input contain PII?”, “does this output include a prohibited URL?” — deterministic checks are faster, cheaper, and more reliable than any prompt-based approach.
But this still leaves the rule management problem unsolved. Where do rules live? How do they stay consistent across multiple projects, agents, and deployment environments? How do you avoid the context bloat that comes from injecting every rule into every prompt, even when most of those rules don’t apply to the task at hand?
At EchoForgeX, we’re addressing this through a project called Praxis — a structured rule library where each rule carries applies_when metadata describing the conditions under which it’s relevant. Instead of embedding a full governance policy into every system prompt, a /discover-rules invocation reads the current task context, matches it against a queryable rule index, and injects only the applicable subset. A rule about validating account identity before billing actions isn’t loaded into prompts for tasks that have nothing to do with billing. Rules are authored once, stored in versioned files, and available to any project that needs them. Context load stays proportional to what the task actually requires.
Rules as First-Class Data
The deeper shift in this approach is treating governance rules as data rather than as prose embedded in configuration. Each Praxis rule is a file with a name, a description, an applies_when tag set, and a body that describes the rule’s intent and enforcement. The rule index is auto-generated and queryable. Task-time rule selection happens against that index, not against a monolithic system prompt.
This has operational consequences beyond context management. Rules stored in versioned files can be reviewed like code — you can see who changed a rule, when, and why. Rule drift, where the rules a team intends to enforce diverge from the rules actually in prompts, becomes visible rather than invisible. Adding a rule to a shared library doesn’t require finding and updating every prompt across every agent and project that should apply it. Removing a rule removes it everywhere at once.
There’s also an auditing benefit that matters for any organization operating under compliance or regulatory requirements. When a governance decision needs to be explained — “why did the agent escalate this message?” — the answer can reference a named rule with a known version, not a fragment of a system prompt that may have changed since the incident. Rules as data are auditable in a way that rules as embedded strings are not.
The key architectural principle is that the model’s role is constrained judgment, not self-governance. Praxis doesn’t remove the model from rule application — it limits the rule set the model must attend to at any moment to the rules that are actually relevant. That’s a narrower problem, and narrower problems produce more reliable outcomes.
What This Means in Practice
If you’re building AI-powered products and relying on prompt-encoded rules for governance, a few principles hold regardless of which specific architectural approach you adopt.
Rules that must be upheld end-to-end should live outside the model’s reasoning loop. Use deterministic pre- and post-checks for anything binary — input classification, output validation, prohibited pattern detection. These are solved problems in traditional software and don’t benefit from being moved into the prompt.
Rule sets that grow beyond a handful of constraints need selection logic. Injecting all rules always is how you hit context limits and degrade adherence for the rules that actually matter on a given task. If your governance layer has grown to dozens of rules, the question of which rules apply to which tasks is a first-class engineering problem, not an afterthought.
Intent parsing and governance should be distinct pipeline steps. Compounding both in a single model call means compounding their error rates. Parse intent, validate the parsed intent against expected values or a deterministic classifier, then route to governance logic that operates on validated input — not on raw user text interpreted at the same time rules are being applied.
Treat AI rule enforcement as a distributed systems problem, because that’s what it is. Silent failures are more common than explicit ones. A model that misapplies a governance rule often still returns a plausible-looking result. Monitor for what the model didn’t catch — missed classifications, constraint violations in outputs, rules that fire less often than they should — not just for errors that surface as exceptions.
The reliability problems in AI rule enforcement are not going away with better models. They’re architectural properties of how attention mechanisms work at context scale. The path forward is infrastructure that doesn’t ask the model to do what it’s genuinely bad at: holding a large, complex rule set in mind while simultaneously parsing ambiguous input and generating structured output against multiple constraints. Externalizing rules, making them selectable by task context, keeping deterministic checks outside the model’s prompt, and treating rules as versioned data rather than embedded text — these are the changes that move the needle on governance reliability.
For more on how we approach AI system design and the tools we build, or to understand how these patterns apply to your own AI integration work, our team is available to discuss the specifics.
At EchoForgeX, we build AI-powered tools and help businesses integrate AI into their workflows. Get in touch to learn how we can help your team work smarter with AI.